Showing posts with label Python. Show all posts

Wednesday, September 18, 2019

Voronoi Mandalas

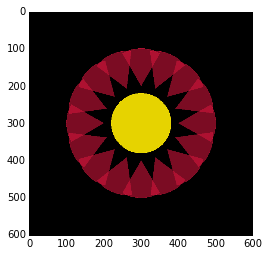
SciPy has tools for creating Voronoi tessellations. Besides the obvious data science applications, you can use them to make pretty art like this:
The above was generated by this code:


I started with Carlos Focil's mandalapy code, modifying the parameters until I had a design I liked. I decided to make the Voronoi diagram show both points and vertices, and I gave it an equal aspect ratio. Carlos' mandalapy code is a port of Antonio Sánchez Chinchón's inspiring work drawing mandalas with R, using the deldir library to plot Voronoi tesselations.

Thursday, April 28, 2016

Lazy Evaluation and SQL Queries in the Django Shell

In Django terms, a QuerySet is an iterable of database records. What's nice about them is that they are evaluated only when you're ready for the results.

This means that even if it takes you a few lines of code to chain multiple queries, the Django ORM combines them into a single query. Less queries mean your database doesn't have to work as hard, and your website runs faster.


Evaluating a QuerySet Repeatedly

Imagine that we work for Häagen-Dazs and have access to their Django shell. We can use this to our advantage by hunting for free ice cream promotions.

Here, we get the active Promo objects. We evaluate the results just to see what promos are available. Then we filter them on the word free.

>>> results = Promo.objects.active()

>>> results
[<Promo: Free Flavors on Your Birthday>, <Promo: 10% Off All Cones>, 
<Promo: Buy 1, Get 1 Free>]

>>> results = results.filter(
>>>     Q(name__istartswith='free') |
>>>     Q(description__icontains='free')
>>> )

>>> results
[<Promo: Free Flavors on Your Birthday>]

The queries generated by the above are:

from django.db import connection

>>> connection.queries
[ {'sql': 'SELECT "flavors_promo"."id", "flavors_promo"."name", 
"flavors_promo"."description", "flavors_promo"."status" FROM 
"flavors_promo" WHERE "flavors_promo"."status" = \'active\' 
LIMIT 21',
  'time': '0.000'},
 {'sql': 'SELECT "flavors_promo"."id", "flavors_promo"."name", 
"flavors_promo"."description", "flavors_promo"."status" FROM 
"flavors_promo" WHERE ("flavors_promo"."status" = \'active\' 
AND ("flavors_promo"."name" LIKE \'free%\' ESCAPE \'\\\' OR 
"flavors_promo"."description" LIKE \'%free%\' ESCAPE \'\\\')) 
LIMIT 21',
  'time': '0.001'}]

There are 2 queries because we evaluated the results twice.

The first query was from the first time we retrieved all the active promos. It's pretty short. It just selects Promo records where promo.status is active.

The second query was from the second time we evaluated results, after we filtered for "free" in the promo names and descriptions.

As a side note, there is a bit of extra work in the second query as the second query still has that WHERE 'flavors_promo'.'status' = 'active' part. One might expect filter() to simply filter on the already-retrieved results rather than hitting the database again. But that's alright because the extra time is negligible.

Before we move on, let's reset the list of queries:

>>> from django.db import reset_queries
>>> reset_queries()

Evaluating a QuerySet Once

Now, let's look at what the queries would be if we only evaluated the results QuerySet once. Let's try building the same QuerySet again. Oh wait, just for fun, let's chain another operation so that we can be really sure that lazy evaluation is happening.

>>> results = Promo.objects.active()

>>> results = results.filter(
...     Q(name__istartswith=name) |
...     Q(description__icontains=name)
... )

>>> results = results.exclude(status='melted')

>>> results
[<Promo: Free Flavors on Your Birthday>]

As you can see, there's only one query:

>>> connection.queries
[{'sql': 'SELECT "flavors_promo"."id", "flavors_promo"."name", 
"flavors_promo"."description", "flavors_promo"."status" FROM 
"flavors_promo" WHERE ("flavors_promo"."status" = \'active\' AND
("flavors_promo"."name" LIKE \'free%\' ESCAPE \'\\\' OR 
"flavors_promo"."description" LIKE \'%free%\' ESCAPE \'\\\') AND 
NOT ("flavors_promo"."status" = \'melted\')) LIMIT 21',
  'time': '0.001'}]

Thanks to lazy evaluation, only one query was constructed, despite chaining multiple operations. That was nice.

Sure, the query could have been more optimal without the AND NOT melted part, but arguably that wasn't Django's fault, it was mine. But it gives me a clue about which operation I didn't need to chain in the Python code.

Next Steps

Try this on one of your projects. Open the Django shell, then try out some queries and see how they are evaluated. In particular, look at queries from one of your slower views.

You can also do similar things with Django Debug Toolbar. However, in the shell you can dissect your Python code line by line, which can be very helpful.

Monday, November 9, 2015

Solving UnicodeDecodeErrors Due to Opening Binary Files


Common Scenario: Walking Directory Tree and Opening Files

A common thing to do in Python is to go through a directory tree, opening each file and doing something with the file's text.

for path in paths:
    for line in open(path, 'r'):
        # Do something with each line of the file here.
        # Go ahead, right inside the for loop.
        # It's a text file, so imagine the possibilities.

Here, we iterate over all the paths in the directory tree. For each path, we open the file for reading. Then we go through each line of the file and do something with it.

The Problem

This works well enough for many situations, but at some point you end up running into a UnicodeDecodeError when you try to open a particular file. Usually, it's because that file isn't a text file: for example, it might be a JPEG or a font file.

Those errors are scary! They look like this:

for line in open(path, 'r'):
_ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ 

self = <encodings.utf_8.IncrementalDecoder object at 0x10349a320>
input = b"\x00\x00\x01\x00\x02\x00  \x00\x00\x01\x00 \x00(\x10\x00\x00&\x00\x00\x00\x10\x10\x00\x00\x01\x00 \x00(\x04\x00\x00N...00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00\x00"
final = False

def decode(self, input, final=False):
    # decode input (taking the buffer into account)
    data = self.buffer + input
>       (result, consumed) = self._buffer_decode(data, self.errors, final)
E       UnicodeDecodeError: 'utf-8' codec can't decode byte 0xad in position 89: invalid start byte

Before you go into a UnicodeDecodePanic trying out all the variants of open, io.open, unicode_open, etc., think about whether the file you're trying to open is even a text file.

The Solution

To solve the problem of accidentally opening non-text files, you can use BinaryOrNot's is_binary function. Just check to make sure the file isn't a binary before attempting to open it, like this:

from binaryornot.check import is_binary

for path in paths:
    if not is_binary(path):
        for line in open(path, 'r'):
            # Do something with each line of the file here.
            # Go ahead, right inside the for loop.
            # It's a text file, so imagine the possibilities.

This is a real-life code example. In fact, it comes from a fix to cookiecutter-django's tests that I just committed this weekend, which comes from Cookiecutter core code.

BinaryOrNot is a package that guesses whether a file is binary or text. I put it together a couple of years ago in order to use it in Cookiecutter. Since then, I've found uses for it over and over in various projects.

More Info

BinaryOrNot on GitHub: https://github.com/audreyr/binaryornot
Project documentation: http://binaryornot.readthedocs.org/

Tuesday, November 3, 2015

Intensive Django Training With the 91st Cyberspace Operations Squadron

Daniel and I just returned from a trip to San Antonio, Texas, where we taught one of our intensive Django training workshops at Lackland Air Force Base.

We prepared a customized version of our curriculum to meet the needs of the 91st Cyberspace Operations Squadron of the US Air Force.

Our intensive Django training at Lackland Air Force Base in San Antonio, Texas.

Teaching such a sharp, enthusiastic group and seeing everyone grasp difficult concepts so rapidly was a huge thrill. As instructors who like challenges, we tend to err on the side of assuming that our students can handle anything, so we threw a lot of very advanced topics at the group, wondering how much would click. On the last day as they were putting their knowledge into practice during hands-on project time, it was apparent that even the hardest parts had made an imprint.

For more info, see Intensive Django Training with the US Air Force, Daniel's detailed blog post about the training experience.

Special thanks to Capt. Jonathan D. Miller for making this possible. It was an honor to work with you and your team.

Tuesday, May 26, 2015

Our Trip to DjangoGirls Ensenada, Mexico

This weekend, Daniel and I drove down to Ensenada, Mexico to speak and coach at DjangoGirls Ensenada. It was a 2-day workshop for women of any level of experience to get a taste of web application development.

A photo posted by Audrey Roy Greenfeld (@pyaudrey) on

The event was organized by DjangoGirlsMX with the help of the US Consulate General of Tijuana and the non-profit Hala Ken.

We asked the US Consulate and Hala Ken about why they decided to get involved. They answered that Django Girls workshops fit perfectly into two of their major areas of interest: new technology and women's empowerment.

We were honored to be invited as guest speakers and appreciative of the opportunity, knowing that we could make a big difference showing women new to Django that we cared.

At the end of the morning session, we gave a talk to inspire attendees to keep going with their programming journey. It was called "Programming Gives You Superpowers." Here are the slides.

Note: for fun we made the cover image a little fancier after the talk, otherwise it's the same :)

It was a fantastic experience getting to spend time with the web development community of Tijuana/Ensenada. So many of the Python Tijuana and Django Girls Tijuana organizers and members drove out to Ensenada and spent the night in hotels to help make this happen. We had fun coaching alongside them after our talk.

My co-author, co-presenter, co-everything husband PyDanny also blogged his account of it: My First Django Girls Event

Finally, we had such a great time that we're now working on planning an upcoming Inland Empire DjangoGirls/RailsGirls event. All are invited to help: RSVP here or here for the May 30 planning session.

Sunday, May 3, 2015

Two Scoops of Django 1.8 is out!

Daniel Roy Greenfeld and I have updated Two Scoops of Django to 1.8, since Django 1.8 is a Long Term Support version.

The book is now available as a PDF. I know this will make a lot of folks happy! The print paperback is coming soon (US and India editions to start).

More info: http://twoscoopspress.org/products/two-scoops-of-django-1-8


I wrote half the book, including some of the rather difficult parts :) I also did the illustrations. The book is filled with a ton of weird cartoons and silly humor.

Enjoy, and hope it's helpful!

Sunday, April 12, 2015

Spring Cleaning for Python Programmers

It's spring again, which means that for Python programmers, it's time to clean out your hard drive.

Instructions:

1. Add these lines to your .bashrc (or other shell rc) file:

alias rmpyc='find . -type f -name "*.pyc" -print -delete'

export PYTHONDONTWRITEBYTECODE=true

The first part gives you a handy rmpyc command to recursively delete .pyc files.

The second part tells Python not to write .pyc files anymore.

2. Source your rc file and run rmpyc from your home directory (on UNIX, from ~). This will delete all the Python bytecode from your home dir onward. You don't need to keep it around because it'll just get rewritten as needed anyway.

3. Delete the virtualenvs that you're not using. (e.g. if you use virtualenvwrapper, delete the directories in ~/.virtualenvs/ that you don't need).

4. If you use VirtualBox, delete the virtual machines that you don't need.

5. Delete the repos that you don't need around anymore.

In my case I freed up 3 GB by removing the .pyc files and 25 GB by removing the virtual machines. I forgot to check how much space my unused virtualenvs took up, but it was probably a non-trivial amount.

My numbers are probably higher than most because my laptop's almost 5 years old and I mess around with random Python packages a lot, but you should still be able to save some space. At the very least, it'll be like squeezing the last paste out of a toothpaste tube.


Note: originally the instructions said the following, but I updated them after advice from Dan Crosta, Glyph, and Kit. Thank you all so much for the tips!

alias rmpyc='find . -type f -name "*.pyc" -print0 | xargs -0 rm -v'

Tuesday, March 24, 2015

Pillow Flowers

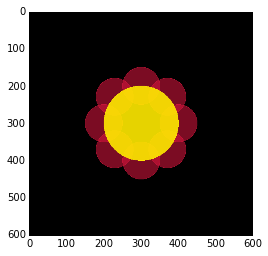
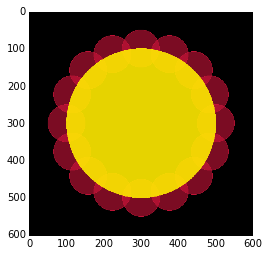
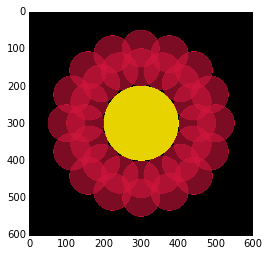
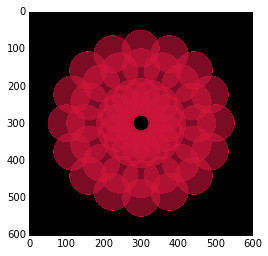
Lately, I've been playing around with drawing flowers with Python and Pillow.

The trick to drawing flowers is to iterate around the petals in polar coordinates, and then convert polar to cartesian for drawing purposes.

Flower Experiment 1 Flower Experiment 1 Flower Experiment 1 Flower Experiment 1 Flower Experiment 1

I demoed some of this at the meetup that I hosted last night, Inland Empire Pyladies' Coding for Artists. There, Danny and I taught participants how to use Pillow, ellipses, rectangles, random number generation, and trigonometry to make basic 2D generative art.

Friday, March 6, 2015

Compressing PDF Files at the Command Line

Sometimes you have to email someone a bunch of PDF files, but you can't keep them in the same email without exceeding Gmail's 25MB limit (or the limit of whatever email service you use). 

Rather than having to split up the email (which isn't ideal in many situations), you can compress the PDF files themselves. Here are a couple of strategies for doing that, both using the wonderful Ghostscript interpreter.
You might remember Ghostscript from your college days.
It's one of those old school things that's still awesome.

In the end, I used ps2pdf to reduce 28MB of PDF files down to 12MB.

ps2pdf

The command-line tool ps2pdf converts .ps files (Postscript) to .pdf using Ghostscript. But you can also pass in a PDF file as input.

If you have Ghostscript installed, you can type this at the command line:

ps2pdf -dPDFSETTINGS=/ebook in.pdf out.pdf

The /ebook setting "selects medium-resolution output similar to the Acrobat Distiller "eBook" setting," which sounds good for documents that need to be screen-readable.

Read more on StackOverflow about what else you can pass into PDFSETTINGS.

Color to Grayscale

Another easy way to get rid of a lot of unneeded PDF size is to convert it from color to grayscale. Color takes up a lot of space and is not needed for many documents.

If you have Ghostscript installed, you can type this at the command line:

gs -sDEVICE=pdfwrite -sProcessColorModel=DeviceGray -sColorConversionStrategy=Gray -dOverrideICC -o out.pdf -f in.pdf

Here, in.pdf is your input file, and out.pdf is your output file.

Did It Work?

The easiest way to tell if it worked is to list the files in the current directory by size:

ls -sS

Compare the size of the input PDF with the output PDF. The output PDF should be smaller, of course.

Other Tools

Here are some other tools to look into if you don't like either of the above approaches.

pdfsizeopt


I always start out by trying to find a Python solution to problems, because then whatever I find becomes a handy little building block for me to use in other Python projects.

Before trying either of the above, I attempted to compress the PDF files with the Python library pdfsizeopt. However, I ran into this error:

error: Multivalent.jar not found. Make sure it is on the $PATH, or it is one of the files on the $CLASSPATH.

I resolved that error by finding the latest Multivalent jar file on the official project page and putting it on my $PATH, but then I got this error:

AssertionError: Multivalent failed (status)

At that point I moved on. That said, if anyone knows how to get around that second error, I'd love to know. It would be great to get pdfsizeopt working.

Shrinkpdf


I also tried out Alfred Klomp's nice shrinkpdf.sh script. If you try it out, experiment with the resolution and the other parameters. (This is actually how I ended up with my color to grayscale solution above.) Study it and play around until you're satisfied with the output.

Monday, February 23, 2015

Recap: Python and Pyladies at SCALE13x

This weekend was the 13th annual SoCal Linux Expo, or SCALE13x. It's held every year at the LAX Hilton.

The Python and Pyladies community booths were side-by-side, with both booths representing members of various Python and Pyladies user groups throughout Southern California.


I spent most of my time on the left side of the Pyladies booth, while Daniel was next door on the right side of the Python booth. Sometimes we crossed over into the opposite booths :)

Audrey and Daniel
The setup sounds formal, but it was more like a friendly Python user get-together at the booths. People often came and stayed just to hang out. It was great to catch up with friends whom I haven't seen in a couple of years. We also got the opportunity to invite a lot of people who came by to future Python/Pyladies meetups throughout SoCal.

Esther of Pyladies LA & Burbank, Audrey and Tiffany of Inland Empire Pyladies

Audrey and Daniel (that's us!), Debra, and Carol (San Diego Pyladies co-organizer).

Special thanks to goodwill for organizing the Python booth, and to Carol Willing for organizing the Pyladies booth.